Hard Links and Symlinks on Object Storage Filesystems
Hard links and symlinks can't work on object storage without an inode table.
Sponsored by Archil
Hard links and symlinks are not features someone bolted onto a filesystem as an afterthought. They fall directly out of the inode model, the bookkeeping system every traditional filesystem uses to track files. Every file's actual data is tracked by an inode, a record holding permissions, ownership, size, timestamps, and the physical location of the data on disk. The file name you see in a directory listing is a pointer, a directory entry, aimed at that inode.
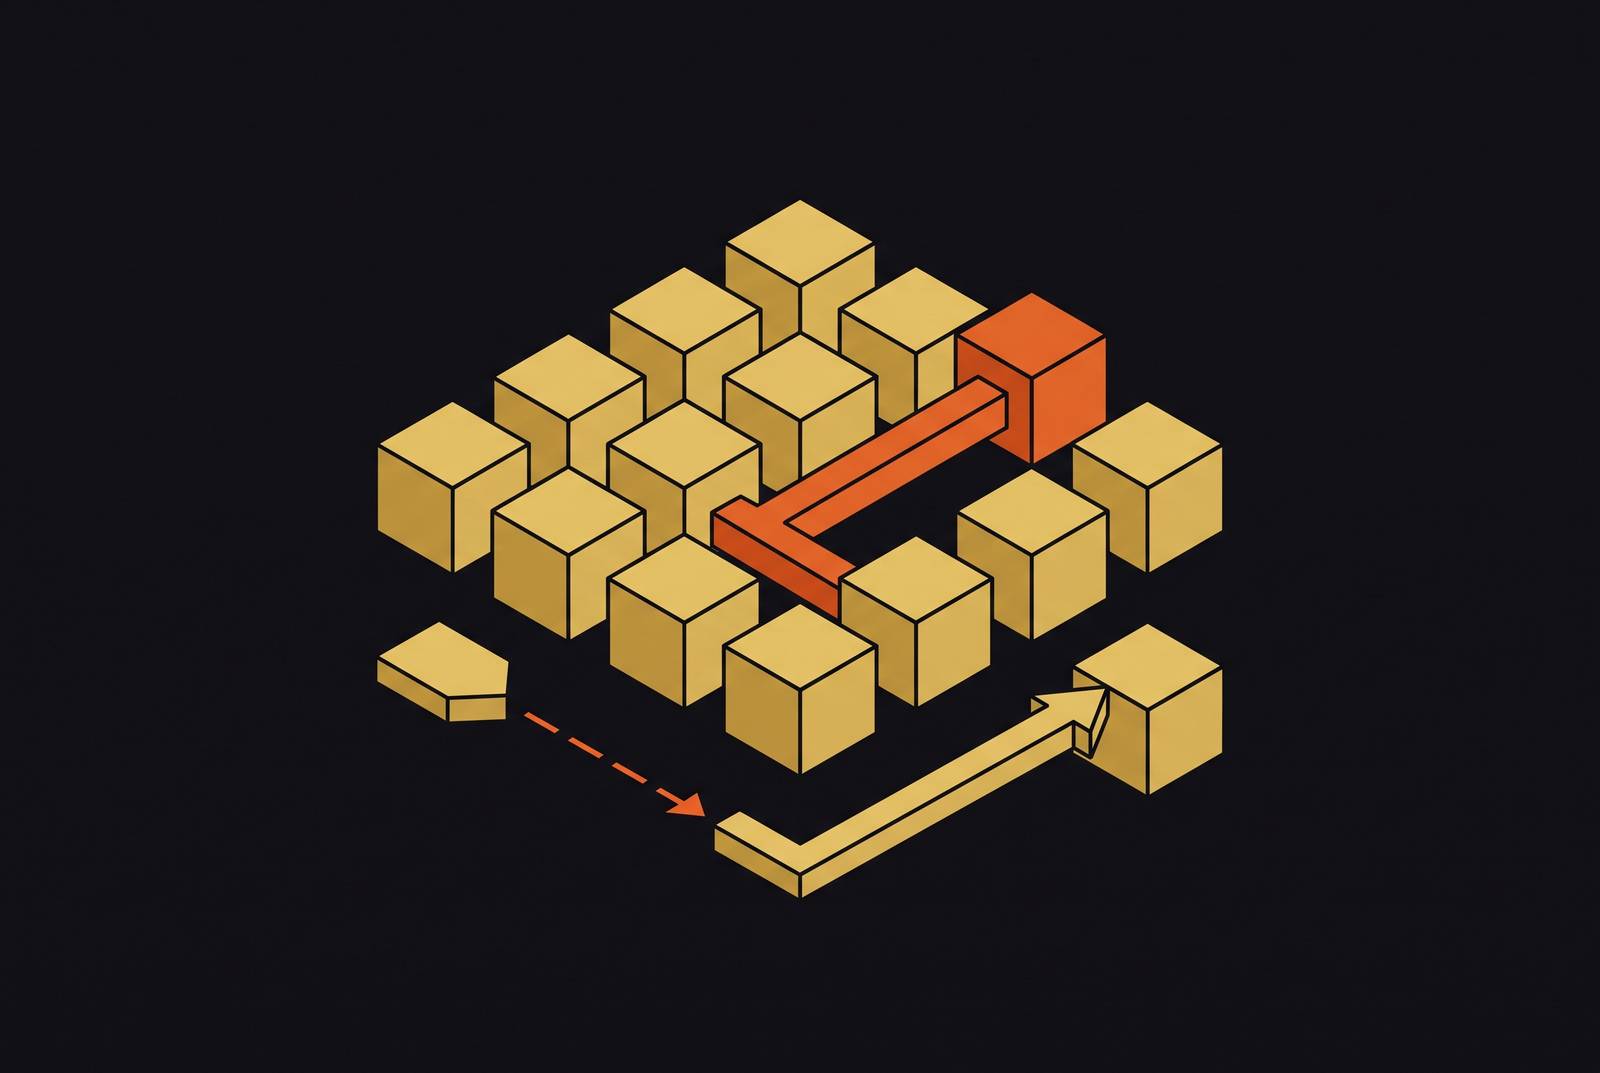
Once you see that separation, hard links stop looking like magic. A hard link is just a second directory entry pointing at the same inode. There's no original and no copy, no "real" file and a secondary alias. Both names are equally legitimate, and the underlying data sticks around until every name pointing at that inode has been removed.
Symlinks work on a different principle. A symlink is its own small file with its own inode, and its content is nothing more than a path string, text pointing at another location. The system reads that path and follows it at the moment someone tries to access it. Because a symlink is just a stored path rather than a hard reference to an inode, it can point across filesystems and at directories, something a hard link can never do.
That asymmetry traces back to how inode numbers work. Hard links cannot cross filesystems, because an inode number only has meaning inside the one filesystem that assigned it. Hard links also can't point at directories. The kernel blocks that outright, both to stop directory loops and to keep the meaning of ".." (the parent directory shortcut) consistent. Symlinks sidestep those two limits by storing a path instead of an inode number, but they pay for it in fragility: move or delete the target, and the symlink is left pointing at nothing, still sitting there, just useless.
That cross-filesystem restriction on hard links is the detail to hold onto. It means a hard link only ever makes sense when both names live inside one filesystem's own inode table. Object storage, as it turns out, has no such table.
Object storage's flat key namespace and inode semantics
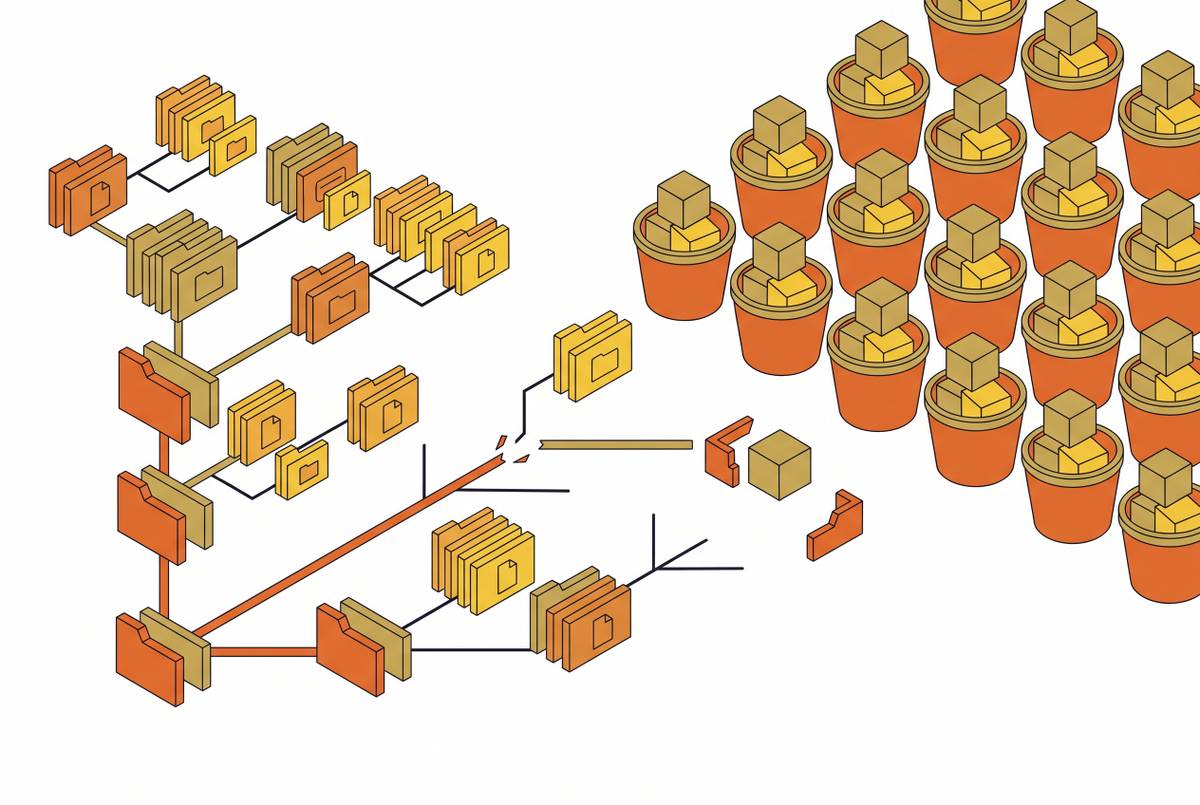
Object storage was built to solve a different problem than the one traditional filesystems solve, and that difference is why hard links and symlinks don't transfer over cleanly. Instead of a directory tree sitting on top of an inode table, object storage uses a flat key pointing at an object made of data plus metadata, accessed over HTTP REST calls. That substitution removes the structure hard links and symlinks need to exist.
The reasoning behind that design is sound on its own terms. Storing data at the scale object stores operate at, without single points of failure, means discarding the classic inode table in favor of something simpler: a key maps to an object, full stop. Operations happen as HTTP calls rather than kernel-level disk operations. There's no inode layer underneath any of it. Nothing exists for a hard link to attach to.
Hard links need two names pointing at one inode inside a single filesystem's numbering scheme. Object storage has no numbering scheme and no "inside one filesystem" to speak of, just a flat space of keys that could, in principle, span the planet. Asking for a hard link on object storage is a bit like asking for someone's apartment number in a city with no addresses, just a very long list of names.
Symlinks fare slightly better in theory, since they only need a stored path string rather than an inode reference. Object storage has no native hierarchy to traverse. Any symlink-like behavior has to be built and maintained by a separate layer sitting on top of the object store, a layer that has to stay consistent with that store on its own.
None of this makes object storage broken. It makes object storage a tool designed for massive, durable, cheap storage of objects by key, a different job than serving as a drop-in replacement for a POSIX filesystem. The gap is architectural, a consequence of the object storage model itself rather than a bug waiting on a patch.
Workflows that break when hard link and symlink support is absent
This gap isn't an abstract footnote for systems architects to debate over coffee. It has a direct, measurable cost for teams running AI training pipelines and dataset versioning workflows, who end up falling back on copying files instead of linking them, which multiplies storage costs and slows things down at the exact moment speed matters most.
Data Version Control, a popular tool for managing machine learning datasets, documents a clear preference order for how it handles files: reflink first, then hardlink, then symlink, and copy only as the last resort. Copy is the fallback nobody wants, and it's what teams get stuck with on object storage, since there's no filesystem layer in between to offer anything higher up that list. Every dataset version that would have been a near-free hard link somewhere else becomes a full, separate copy of potentially enormous files instead.
The pain appears again in everyday metadata operations. A single LIST call or a single stat call against standard object storage is a network round-trip across the network, incurring latency that a near-instant lookup on local disk never pays. That's invisible in a benchmark testing one file. It stops being invisible the moment a training pipeline issues thousands of these calls per epoch, because thousands of tiny network round-trips add up to real, measurable training delay.
Put those two problems side by side: datasets get copied instead of linked, storage bills grow for no good reason, and routine metadata chatter turns into a latency tax paid on every single epoch. That latency tax is precisely the kind of cost a filesystem layer sitting between object storage and your training code is supposed to eliminate, and precisely why the architectural choices behind that layer matter.
The architectural choices a filesystem must make to support POSIX link semantics on object storage
Getting hard links and symlinks working on object storage is a cluster of interlocking choices about where metadata lives, how it stays consistent, and which POSIX guarantees get genuinely preserved versus merely gestured at.
The foundational choice is metadata separation. Since object stores carry no inode table of their own, the filesystem layer has to run its own metadata store, one that maps names to inode-like structures and stays consistent with the underlying objects even through concurrent writes, node failures, and cross-region replication. That's a lot of responsibility for a layer that, on a traditional filesystem, the kernel just handles.
Hard link support specifically demands that this metadata layer track reference counts, the same job a traditional inode's link counter does, just reimplemented entirely in software above the object layer. The underlying object can't be deleted until every name pointing at it has been removed, and keeping that count accurate under real-world failure conditions is the hard part.
Symlinks ask less of the system but still ask plenty. The metadata layer has to store and resolve path strings and handle dangling links gracefully when a target moves or disappears. That's architecturally lighter than reference counting, but it still needs a namespace that's consistent and queryable in a way object storage, on its own, simply isn't built to offer.
Then there's immutability, where the object storage model and the hard link model actually collide head-on. Object stores treat each object as an immutable blob tied to one key. Replacing an object means writing an entirely new one, not editing bytes in place. Hard links, by contrast, depend on multiple names pointing at one mutable data location that can be updated without touching the names pointing at it. Those two ideas sit in structural incompatibility, so reference counting in a separate metadata layer has to stand in for what a mutable inode would otherwise do on its own.
A separate metadata engine, something fast like Redis or a distributed key-value store, can solve that reference-counting problem. It's an infrastructure dependency that has to be sized correctly, replicated for durability, and operated right alongside the object store itself. Sub-millisecond metadata latency is achievable when that engine sits close to compute. The moment metadata operations have to round-trip to a remote store, the very latency problem that made object storage attractive in the first place creeps right back in.
Amazon's own managed offering illustrates how firm this line is drawn in practice. S3 Files, AWS's own managed file service, states outright that it does not support hard links, with each file in the filesystem mapped to a single S3 object key. If AWS, building on its own storage, draws that line, it's a solid signal that hard link support on object storage is a genuinely hard architectural problem, not an oversight anyone just forgot to fix.
All of this points toward a single working definition of what "doing it right" looks like: full POSIX semantics, preserved without asking anyone to touch their code.
Full POSIX semantics on object storage in a working system
A filesystem that actually supports hard links and symlinks on object storage has to preserve the full POSIX contract: atomic rename, flock and fcntl locking, mmap, fsync, hard links, symlinks, and sparse files, all without requiring code changes, a new SDK, or a data migration. The entire point of POSIX compliance is that code written years ago, against a completely different storage system, keeps running without modification.
That no-migration requirement isn't a nice-to-have tacked on for convenience. Teams sitting on petabytes of data in S3, GCS, R2, or Azure Blob cannot realistically move all of it just to gain filesystem semantics. The filesystem layer has to mount directly on top of the existing bucket and treat that bucket as the actual source of truth, the real destination rather than a staging area on the way to somewhere else.
Performance has to hold up under that constraint too. Reads need to hit an NVMe cache at sub-millisecond speed, so the metadata round-trip cost described earlier doesn't quietly reappear in production. A cache miss pulls data from the bucket and caches it going forward, which keeps the bucket authoritative without forcing every single read to pay the network tax. Writes need to replicate before confirming back to the caller, preserving durability, then flush to the bucket asynchronously in the background. That pattern is what makes atomic rename actually work, since the rename commits in the metadata layer first and the object store catches up afterward rather than the two racing each other.
Hard link support in a system built this way means the metadata layer tracks reference counts against the objects the bucket holds, and once that count hits zero, the object becomes eligible for deletion, mirroring traditional inode behavior without needing the underlying objects to ever be mutable. Symlink support means storing and resolving path strings across the full namespace, including symlinks that point at directories, the single most common pattern in production use for things like version management, dataset aliasing, and checkpoint routing.
Cloud-agnosticism belongs on this list too, and it belongs there as a correctness requirement, not a sales pitch. An implementation that only delivers POSIX semantics on S3 forces any team running multi-cloud or multi-region training infrastructure to run a different filesystem solution per cloud, which quietly reintroduces the exact data-movement problem the filesystem was supposed to solve in the first place.
Evaluation criteria for object storage filesystem link support
Every architectural choice covered so far turns into a direct question to ask any object storage filesystem before committing to it, and the honesty of the answers tells you whether a given implementation preserves real semantics or just approximates them. Start with whether hard links are supported at all: even AWS's own managed S3 Files service drops them at the managed-service level, so any filesystem that leaves them out should say so, and anyone relying on DVC or rsync-style snapshot backups needs that answer before signing on.
Ask how metadata is stored and how consistent it actually is. A metadata engine that's only eventually consistent with the object store will produce race conditions the moment two processes write concurrently, so get a straight answer on whether atomic rename is genuinely guaranteed rather than just listed as a design goal on a slide somewhere.
Ask what metadata latency looks like in production. Sub-millisecond metadata performance requires that layer to sit physically close to compute. A metadata store that has to round-trip to a different region brings back the exact bottleneck object storage filesystems exist to remove.
Ask whether the full POSIX contract is covered, meaning atomic rename, flock and fcntl, mmap, fsync, hard links, symlinks, and sparse files, or whether only a comfortable subset made the cut. An implementation that skips part of that list tends to break existing code quietly rather than loudly, the way PyTorch's rename pattern broke on S3 for years without throwing an obvious error anyone could point to.
Ask whether adopting it requires data migration, an ETL pipeline, or changes to existing code. A filesystem that demands moving data out of an existing bucket to get POSIX semantics isn't really offering an overlay at all, it's asking for a migration, and the operational cost of that migration often outweighs whatever benefit it was supposed to deliver.
Ask whether it's cloud-agnostic. Anything tied to one cloud's own managed service, whether that's S3 Files on AWS, CPFS on Alibaba, or OBS on Huawei, can't serve a team running multi-cloud or multi-region training infrastructure, and teams operating across multiple regulatory regimes need something that mounts the same way everywhere.
Finally, and this is the one most evaluation calls skip right past, ask where the data actually lives once the filesystem is mounted. A system that keeps a persistent copy of data outside the customer's own bucket introduces data residency and sovereignty risk that has nothing to do with hard links or symlinks and everything to do with who legally controls that data. The bucket should remain the source of truth throughout, and if access to the filesystem layer is ever revoked, the data should be sitting exactly where it started, untouched and still the customer's own.
This article is sponsored by Archil.