Atomic Rename Guarantees Across Cloud Storage Backends
Cloud storage backends handle atomic rename differently.
Sponsored by Archil
Atomic rename means something different on every major cloud storage backend, and that difference quietly shapes whether your checkpoint pipeline survives a crash or your table format needs a side car of extra infrastructure. Some clouds solved rename at the architecture level. Others left it as homework for the application layer. This piece walks through what each backend actually guarantees, where the guarantees stop, and why the choice you make at bucket creation time follows you for the life of the system.
Why rename is structurally harder on object storage than on a local filesystem
On a local POSIX filesystem, renaming a folder is almost insultingly simple: update one metadata pointer, and the data underneath never has to move at all. The directory entry changes address. The files inside don't pack a single box.
Cloud object storage never built real directories in the first place, so it doesn't get that luxury. What looks like a folder structure is really just a naming convention, a shared prefix stitched across a flat sea of keys. Asking it to "rename a directory" finds no pointer to flip. The system has to copy every object living under the old prefix to a new one and then delete the originals, an operation that scales with however many objects you've got and cannot be made atomic at the storage layer no matter how clever the engineering.
A widely-cited Hacker News thread on S3 Files noted that scalable metadata filesystems like Colossus, Tectonic, ADLS Gen2, and HopsFS are designed either around solving rename at scale or working around it at higher levels in the stack. Either design the namespace itself to make rename fast and atomic, or accept that it won't be and build workarounds further up the stack.
That fork in the road is the entire plot of this article. Every backend covered below picked one of those two paths, and the path they picked determines what breaks, what costs extra, and what your engineers end up babysitting.
Standard S3: why copy-then-delete is still the default
General-purpose S3 buckets have never supported atomic rename. That hasn't changed, and it isn't about to. S3's whole model is key-based: every object stands alone, and there's no mechanism for bundling an operation across multiple keys into one atomic transaction. Renaming a prefix has always meant copy-then-delete, with a window in the middle where the data exists in neither a fully old nor fully new state.
August 2024 did bring a real upgrade, just not the one people sometimes assume. S3 conditional writes went generally available, giving developers PUT if absent (If-None-Match: *), a way to stop duplicate writes and run optimistic locking on individual objects without needing an external coordinator standing guard. For Delta Lake specifically, this lands somewhere useful: its atomicity depends on a commit-file naming convention, where a writer trying to commit a new version attempts to create a specifically named JSON file, and if that file already exists, the writer knows it lost the race, re-reads, and tries again. That pattern needs atomic put-if-absent to work safely, and S3 can now provide it natively, which quietly retires the historical need for a coordinating service like DynamoDB in that specific role.
Keep the celebration proportional, though. Conditional writes solve atomicity for a single object, not atomicity for a directory full of them. An agent running on standard S3 that wants to rename a folder still has to copy every file inside it, one by one. The S3 Files launch made that limitation concrete by shipping without rename support in the first place. Object-level safety and directory-level rename are two separate problems, and August 2024 only answered one of them.
S3 Express One Zone: what the June 2025 RenameObject API does and does not cover
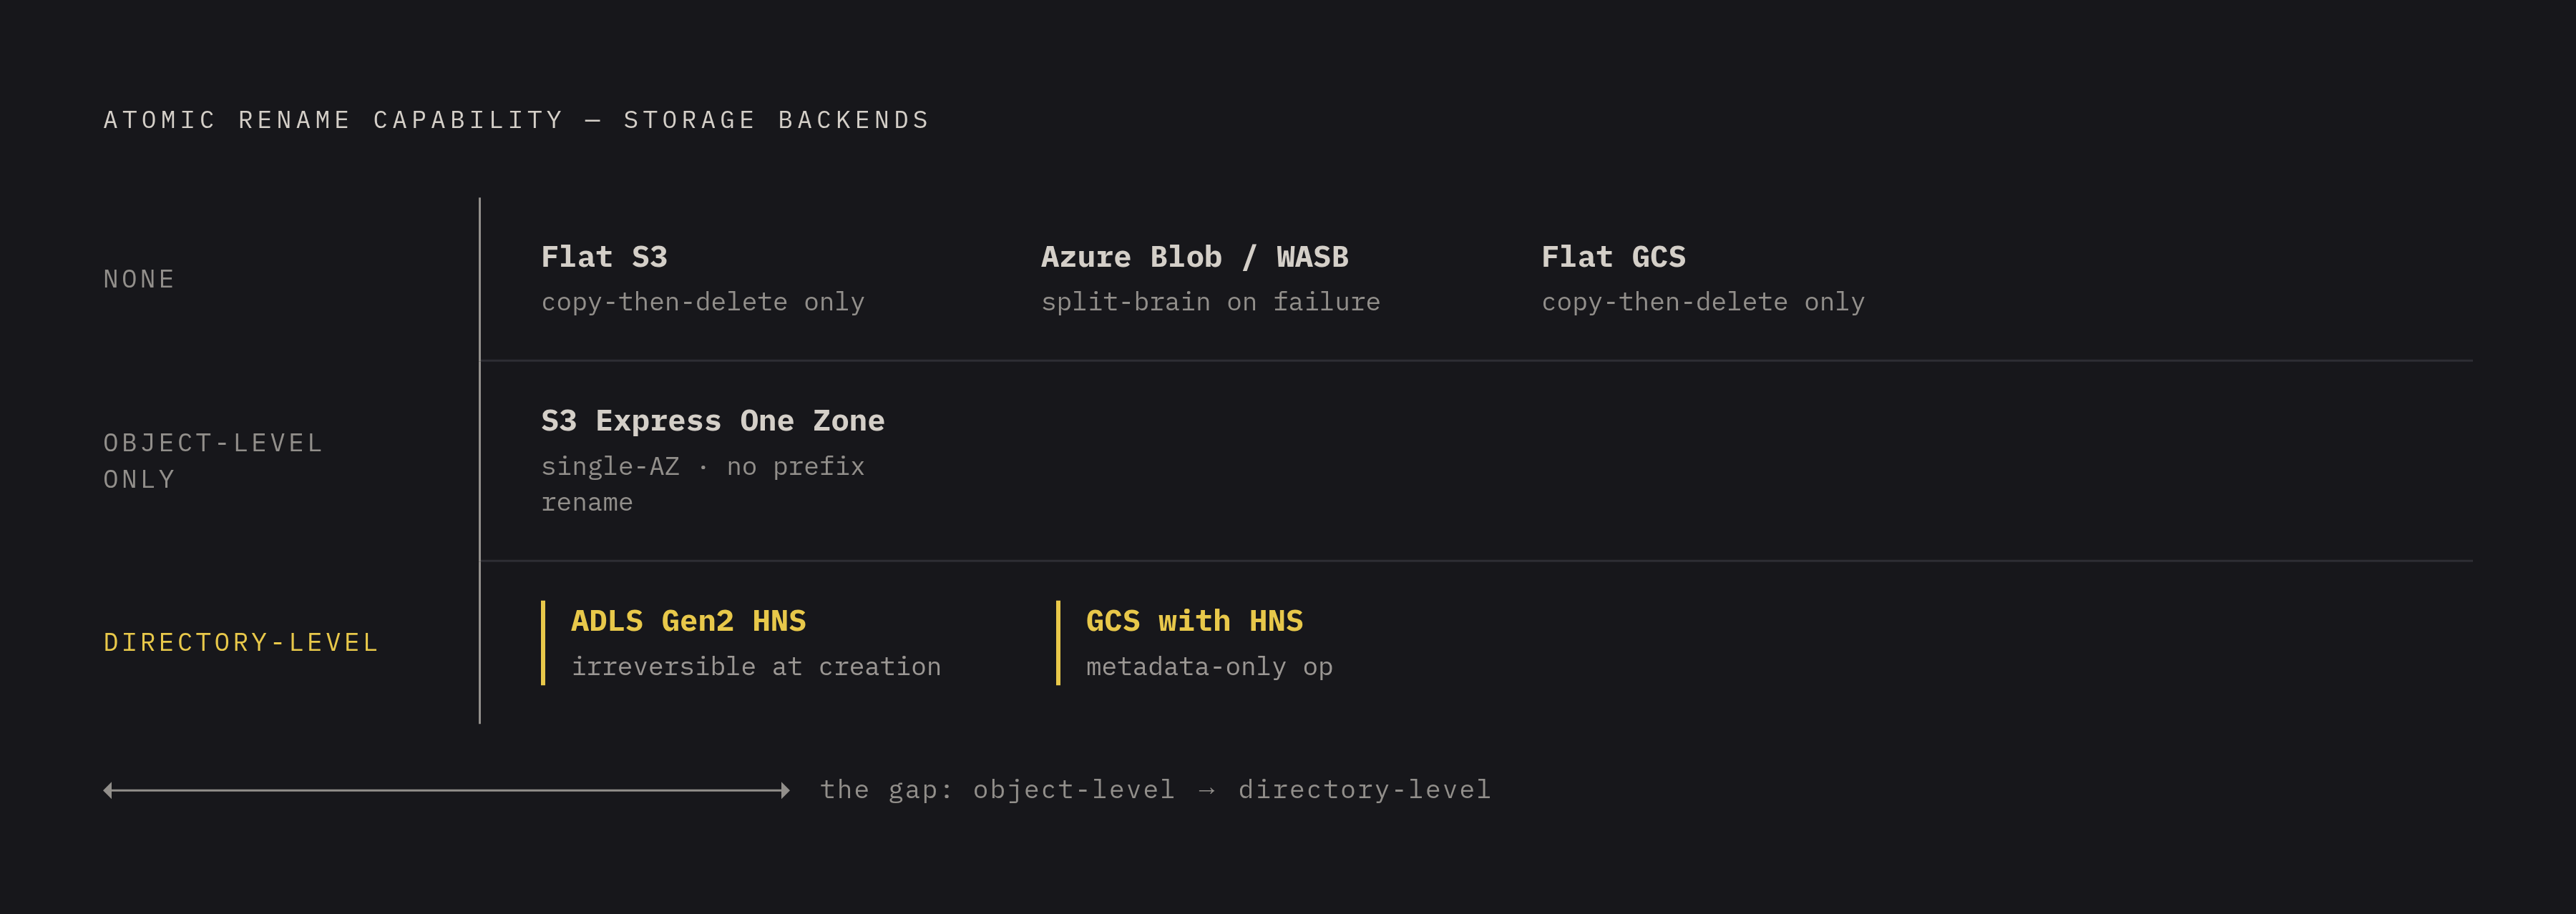
On June 18, 2025, Amazon S3 Express One Zone picked up genuine atomic object rename through a new RenameObject API. This is where the "but" matters: the capability lives in directory buckets, a distinct bucket type built for S3 Express One Zone, not a folder sitting inside an ordinary general-purpose bucket. Conflating the two is an easy mistake, and an expensive one if it shapes your architecture plans.
What RenameObject actually does is refreshingly boring in the best way. It takes an existing object's name as the source and a new name as the destination, both within the same directory bucket, no data movement involved, a single operation completing in milliseconds no matter the object's size. Renaming a 1-terabyte object now takes milliseconds in Express One Zone, while the equivalent copy-then-delete dance on general-purpose S3 takes hours, so one operation is invisible to your pipeline and the other becomes the reason it missed its window.
The feature is available in every region where this storage class itself is offered, and it's reachable through the AWS SDKs, the AWS CLI, the AWS Management Console, the Amazon S3 API, and a compatible Mountpoint for Amazon S3 client version. Express One Zone is a single-AZ storage class, tuned for high-throughput, latency-sensitive workloads. The availability trade-off that comes with living in one zone, combined with the directory-bucket requirement, means teams can't just swap it in for general-purpose S3 across every workload.
And the gap that remains is the one that sets up everything still to come. RenameObject operates on individual objects inside a bucket. It does not rename a folder or prefix as a single atomic unit. The directory-rename problem that actually matters for checkpoint pipelines and table formats has been solved at the namespace level on GCS and on ADLS Gen2, but it has not yet been solved on any general-purpose S3 bucket.
Azure Blob Storage and ADLS Gen2: the irreversible namespace decision that changes everything
Azure's two-tier design is flat Blob Storage by default, with ADLS Gen2 and Hierarchical Namespace (HNS) as an opt-in that requires a structural commitment at account creation, since migrating to HNS requires provisioning a new account and moving data. The rename guarantee isn't a feature you bolt onto an existing account later; it's a structural commitment made at account creation, full stop on options after that.
Documentation from Hortonworks and Cloudera on cloud data access spells it out without hedging: by default, Azure Blob Storage (WASB) folder rename is not atomic. A failure partway through leaves some folders sitting in the original directory and some already moved to the new one, a split-brain mess that someone has to clean up by hand.
Flipping on Hierarchical Namespace changes the entire equation. ADLS Gen2 with HNS enabled makes renaming or moving a directory a single metadata operation, regardless of how many objects live inside it, O(1), atomic, done in under a second. The gap in practice is almost comic. Renaming a prefix holding millions of objects on flat Blob needs roughly twice that many individual copy-and-delete operations and eats tens of minutes. On ADLS Gen2 with HNS, the same rename is one metadata operation, finished before you've looked away from the screen.
The hard constraint sits right at the start of the process. You cannot enable Hierarchical Namespace after the storage account already exists. Migrating means standing up a new account and moving the data over, a one-time, high-friction project with no undo button once it's done. That irreversibility is what turns "should we enable HNS?" from a routine operational checkbox into an architectural decision that has to be settled before the first byte gets written. Teams that picked flat Blob Storage before they understood rename semantics are now stuck choosing between living with workarounds indefinitely or absorbing a migration project they didn't budget for.
The ripple effect reaches into the analytics stack too. The hadoop-azure filesystem layer, the thing powering Spark and Hive on Azure, simulates folders on top of what is, underneath, still flat storage. Pipelines built on the assumption of atomic rename and consistent directory listing are quietly running on non-atomic behavior unless HNS has been switched on.
GCS Hierarchical Namespace: how a dedicated folder-level rename capability makes directory rename a metadata-only operation
Google Cloud Storage arrived at roughly the same conclusion as Azure, by a parallel road. GCS offers its own Hierarchical Namespace, with a dedicated folder-level rename capability sitting alongside object-level tools. The Objects: move method, along with SDK equivalents like moveFileAtomic in Node.js, MoveObject in C++ and C#, and moveBlob in Java, delivers atomic object-level rename inside an HNS bucket, with optional generation-match preconditions available to head off race conditions.
The precondition pattern in the GCS documentation is tidy: if the target object doesn't exist yet, set a DoesNotExist precondition; if it already exists, match against its generation number. That way the operation fails safely instead of silently clobbering something a competing writer just finished.
HNS on GCS isn't just about rename semantics either. It delivers meaningfully higher throughput for filesystem-like workloads compared to flat-namespace GCS, which matters directly for training pipelines firing off large volumes of concurrent metadata operations. AssemblyAI's experience is the sharpest data point here: combining GCS HNS with Cloud Storage FUSE produced more than a tenfold increase in throughput from GCS, with training speed improving 15 times over. Google's own benchmarks separately show substantially faster checkpointing on HNS buckets, the kind of number that changes how long a training run takes to finish.
As with Azure, this is a bucket-level configuration decision, and teams adopting it should treat it as permanent for that bucket. Cloud Storage FUSE lets GCS HNS buckets mount as local filesystems on VMs or GKE pods with no code changes required, handing training code the same POSIX-style interface it already expects. Archil, a serverless filesystem layer that mounts S3 and GCS buckets as a native POSIX filesystem for AI and data-intensive workloads, operates on the same principle of zero-copy access without requiring migration or code changes.
Checkpointing and Training Pipeline Reliability
Rename is the mechanism that decides whether a checkpoint commit is safe. Without atomic rename, a partial write leaves the checkpoint directory in an inconsistent state, and recovering from a failed node means restarting training from a much earlier point rather than resuming from the last save.
Checkpoint writes in large-scale training arrive in bursts, synchronized across many nodes at once. The storage layer has to absorb a sudden flood of writes and commit all of them atomically, or the checkpoint simply isn't trustworthy. On flat-namespace storage, a crash in the middle of a rename-based commit can leave some files at the old path and some at the new one. Training can't safely determine which state is the real one, and the only safe move is a full restart.
Meta's experience with Tectonic shows what that bottleneck looks like at scale: the company found 56% of GPU cycles sat stalled waiting for training data because the storage layer couldn't keep pace, with exabyte-scale datasets too large to keep local to the training hardware. Atomic rename knocks out one piece of that problem directly. When a checkpoint commit is a single metadata operation, it finishes in milliseconds instead of scaling with dataset size, and there's no inconsistency window left open for a crash to strand a run inside.
The storage choice made at account or bucket creation, flat S3, S3 Express One Zone, flat Blob, ADLS Gen2 with HNS, flat GCS, or GCS with HNS, decides whether checkpoint safety comes built into the storage or has to be engineered on top of it by hand, a decision that either saves engineering time for years or quietly demands it.
How table formats inherit the rename problem from the backend they sit on
Apache Iceberg and Delta Lake get described as cloud-agnostic, and in a sense they are. But both resolve concurrent-write safety through commit protocols that ultimately lean on the backend's rename or conditional-write semantics, so the same table format behaves differently depending on where it's deployed.
Iceberg's commit protocol depends on atomic rename for safe metadata updates, and that works cleanly on backends that provide it, HDFS and ADLS Gen2 among them. On standard S3, concurrent writers can collide unless a DynamoDB-based lock table gets added as an external coordinator. Delta Lake takes a different route, using a commit-file naming convention: a writer claiming version N tries to create a specific JSON file, and if that file already exists, the writer lost the race and has to retry. That pattern needs atomic put-if-absent, and general-purpose S3 now provides it natively through the August 2024 conditional writes, which removes the need for an external lock service in this particular case.
The workaround isn't free when it's still required. A DynamoDB lock table for Iceberg on S3 means an extra dependency, extra operational overhead, and extra cost, maintained for as long as the data lake itself exists.
The direction of travel in 2025 and 2026 points toward collapsing some of this complexity. Pressure is building toward real interoperability between Delta and Iceberg: Databricks has proposed that Delta Lake 5.0 adopt the Iceberg v4 adaptive metadata tree as its native content metadata, readable and writable by both formats' clients with no translation layer in between. UniForm already publishes Delta as Iceberg, and XTable translates between formats in both directions with no format designated as the "real" destination. None of that makes the backend's rename semantics less important. If anything, a shared metadata layer still has to commit changes atomically somewhere, and that somewhere is still the storage backend underneath it.
That leaves teams wanting one Iceberg or Delta workload to run cleanly across S3, GCS, and Azure Blob with a genuine fork to navigate: engineer to the lowest common denominator, S3's flat namespace plus a lock table, or commit to backend-specific capabilities like HNS on Azure or HNS on GCS and accept the migration cost that comes with choosing it. There's no backend that makes this decision disappear.
This article is sponsored by Archil.
Sources
- Amazon S3 Express One Zone now supports atomic renaming of objects with a single API call - AWS
- Renaming objects in directory buckets - Amazon Simple Storage Service
- Atomic Rename as a Crash-Safety Primitive · Ground State Storage
- GCS Hierarchical Namespace Accelerates AI/ML Workloads
- Open access to the Proceedings of the 22nd USENIX Symposium on Networked